Assumptions and verification
Claim revision: catalog:274dcfa80485a913443947a8edc732313fcf1cce8d8a3ccf1ecbb8b426f8526c
Standing assumptions: The work is a six-page prose rejoinder (Observational Studies 11.1 (2025): 85-90). Journal pp. 85-90 are PDF pp. 2-7, so printed page = PDF page + 83; PDF p. 1 is a Project MUSE cover page. It contains no theorem, proposition, lemma, numbered or displayed result, proof, estimator formula, table or figure; its only formula is the inline $n^{1/4}$ on p. 88 (PDF p. 5); it has one footnote and one reference (Robins and Ritov 1997). All seven page images were read, and everything quoted from the rejoinder below was transcribed from them.
(S1) Setting of the two recapitulated results, Section 1, p. 85 (PDF p. 2): 'When a practitioner aims to estimate averages of bounded potential outcomes (e.g., the average treatment effect on a binary outcome) in a setting where both ignorability and positivity are known to hold after adjusting for at least one continuous covariate, the following statements are true:' Two bullets follow; they are targets P047-T1 to P047-T3.
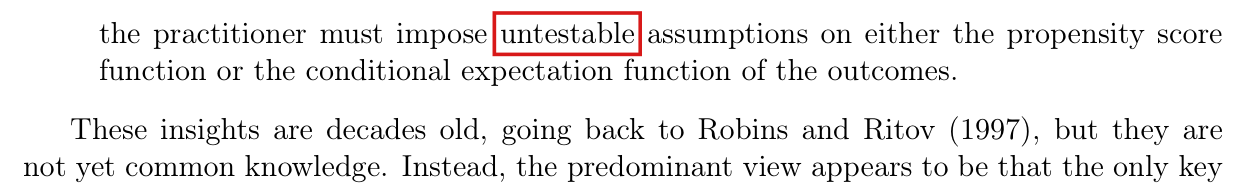
(S2) Status of the two bullets. Section 1, p. 85 (PDF p. 2): 'We believe this broader perspective is important, and the comments serve as complements to the somewhat narrow points we made in our paper. However, we believe these narrow points are of great consequence, and we find it useful to briefly recapitulate them here.' Section 1, p. 86 (PDF p. 3): 'These insights are decades old, going back to Robins and Ritov (1997), but they are not yet common knowledge.' 'Our paper' is the target article, 'Nonparametric identification is not enough, but randomized controlled trials are', Observational Studies 11.1 (2025): 3-16 (work P046 in this audit). It is not among the staged sources of P047 and is not in the rejoinder's reference list. The rejoinder calls ignorability and positivity 'the identifying assumptions' (p. 86, PDF p. 3: 'While the identifying assumptions indeed often are more credible in an RCT, the position that this is the only important difference is misleading').
(S3) What the rejoinder does not define. It uses no symbols and defines none of: potential outcomes, ignorability, positivity, propensity score, estimator, 'uniformly root-$n$ consistent', 'asymptotically normal', 'finite-sample valid', 'uniformly consistent', 'uniform (i.e., honest)', width. The definitions the bullets inherit are those of the target article, transcribed here from its page images (runs/P046/staged/pages/p-04.png to p-06.png; in that article printed page = PDF page + 1). Target article, Section 2, p. 5 (its PDF p. 4): 'We assume that we have an i.i.d. sample $(W_i, Y_i, X_i)$ from some large population, where $Y_i$ and $X_i$ are binary, and $W_i$ is drawn from a continuous distribution (either known or unknown). As above, $Y_i$ is the outcome, $X_i$ is the treatment, and $W_i$ is the covariate.' 'For our discussion, we invoke the consistency assumption (c.f., the stable unit treatment value assumption), $Y_i = (1 - X_i)Y_i(0) + X_iY_i(1)$, and unconfoundedness, $Y_i(x) \perp\!\!\!\perp X_i \mid W_i, \quad \forall x \in \{0, 1\}$.' 'We define the propensity score function as $\pi(w) = \Pr(X_i = 1|W_i = w)$, and assume that positivity holds, meaning that $\delta < \pi(W_i) < 1 - \delta$ with probability one for some positive $\delta$. Without loss of generality, the parameter of interest is the average potential outcome under treatment: $\mu = \mathrm{E}[Y_i(1)]$.' Target article, p. 6 (its PDF p. 5): 'Proposition 1 Suppose we have a study for which consistency, unconfoundedness, and positivity hold. Without further assumptions, there exists no estimator of $\mu$ that is uniformly consistent.' 'The focus on uniform consistency allows the population distribution to depend on $n$.' 'in an RCT, the propensity score function, $\pi(w)$, is known to the researcher, since it is specified by the experimental design.' 'Proposition 2 Suppose the propensity scores are known. Then the Horvitz–Thompson estimator $\hat\mu = n^{-1}\sum_{i=1}^{n}[\pi(W_i)]^{-1}X_iY_i$ is unbiased, uniformly root-n consistent, and asymptotically normal for $\mu$.' Target article, p. 7 (its PDF p. 6): 'This confidence interval is finite-sample valid, meaning that its coverage is guaranteed to be greater or equal to its nominal level even in small samples.' The external check recorded in runs/P047/settle/settled.json (item P047-A003) read the same positivity assumption in the preprint, arXiv:2108.11342v2 ('$\delta < \pi(W_i) < 1 - \delta$' 'with probability one for some known positive $\delta$ bounded away from 0').
(S4) Formal setting used in the targets. This is the notation of the audit's validators; the rejoinder prints none of it. Units $i = 1, \ldots, n$ are i.i.d. copies of $(W, A, Y(0), Y(1))$: $W$ is the covariate, with a continuous distribution; $A \in \{0, 1\}$ is the treatment ($X_i$ in the target article); $Y(0), Y(1)$ are the potential outcomes; the observed outcome is $Y = AY(1) + (1 - A)Y(0)$ (consistency). Ignorability: $A \perp Y(a) \mid W$ for $a = 0, 1$ (the target article's unconfoundedness; the validators write the joint form $A \perp (Y(0), Y(1)) \mid W$, and their derivations use only $E[AY(1) \mid W] = e(W)\,E[Y(1) \mid W]$ and $E[(1 - A)Y(0) \mid W] = (1 - e(W))\,E[Y(0) \mid W]$). Propensity score: $e(w) = \Pr(A = 1 \mid W = w)$ ($\pi(w)$ in the target article). Bounded potential outcomes: $|Y(a)| \le B$. Positivity: $\varepsilon \le e(W) \le 1 - \varepsilon$ almost surely. $B$ and $\varepsilon$ are fixed constants common to the model. Estimands: $\tau = E[Y(1) - Y(0)]$ (the rejoinder's example, 'the average treatment effect') and $\theta = E[Y(1)]$ ($\mu$ in the target article). All probabilities and expectations are over repeated i.i.d. samples. $\log$ is the natural logarithm. 'Known' propensity score: the estimator and the interval may use the function $e$. 'Not known': they are functions of the observed sample $(W_i, A_i, Y_i)_{i \le n}$ alone, the same for every law in the model.
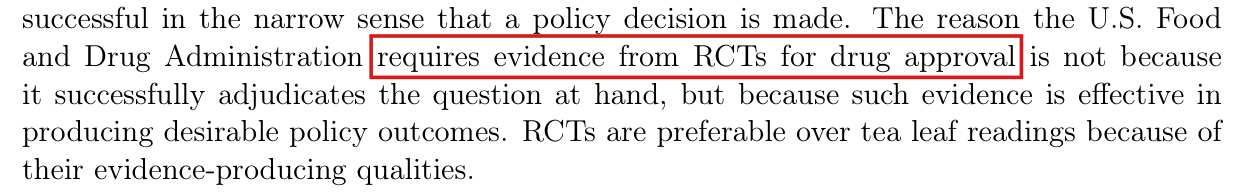
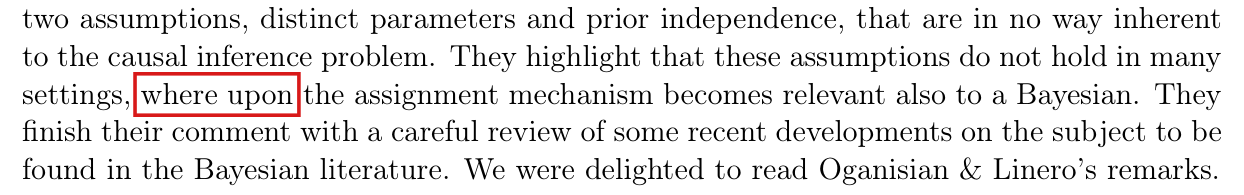
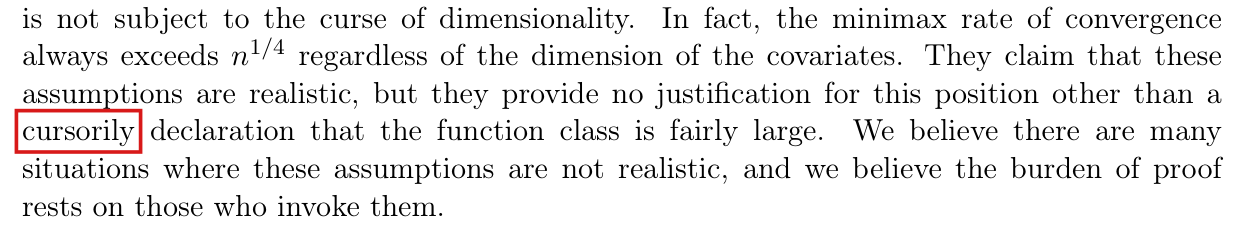
(S5) What is not a target. No confirmed error changes a mathematical statement, a formula or a proof step. The four confirmed errors, all Minor (rate/ratings.json), are P047-E001 (the assertion about what the U.S. Food and Drug Administration requires, p. 89), P047-E002 (the word forms 'where upon', p. 87, and 'cursorily declaration', p. 88), P047-N001 (licence wording on the distributor's cover page, PDF p. 1) and P047-N002 (the city in an author address, p. 85). P047-A001, P047-A002 and P047-A003 are not confirmed and P047-N003 is a clarity note. There is therefore no corrected-statement, counterexample or as-printed target. Headline claims P047-H3, P047-H6, P047-H7 and P047-H8 are interpretive, or concern what the commentaries and the target article say. Two further headline claims are mathematical in character but cannot be stated from this work, and are not targets. P047-H4, Section 2.5, p. 88 (PDF p. 5): 'Namely, that it belongs to “the class of multivariate real-valued cadlag functions with a bound on the sectional variation norm.” This class is sufficiently small so that it is not subject to the curse of dimensionality. In fact, the minimax rate of convergence always exceeds $n^{1/4}$ regardless of the dimension of the covariates.' The function class is named only by a quotation from a commentary that is not staged; the rejoinder defines neither the class, the sectional variation norm, the quantity estimated, the loss nor the sampling model, attaches no hypothesis and gives no citation; and the validator did not verify the entropy or minimax premises (validated.json, P047-A001, what_is_not_established). P047-H5, Section 2.5, p. 88 (PDF p. 5): 'However, the price paid for superefficiency is that Wald-type intervals centered on the estimator are no longer uniform asymptotic confidence intervals, even when the propensity score and outcome regressions are cadlag with bounded sectional variation norm.' The estimators are described only in Section 8 of the same unstaged commentary (validated.json, P047-A002).
Effective claim (source TeX): [Printed: Section 1, p. 85 (PDF p. 2)] 'When a practitioner aims to estimate averages of bounded potential outcomes (e.g., the average treatment effect on a binary outcome) in a setting where both ignorability and positivity are known to hold after adjusting for at least one continuous covariate, the following statements are true: • If the propensity score is known, such as in a randomized controlled trial (RCT), there exist simple estimators that are uniformly root-$n$ consistent and asymptotically normal. Confidence intervals based on these estimators are finite-sample valid and their widths shrink at a root-$n$ rate.' The target is the second sentence of the bullet, with the exact finite-sample facts about the estimator on which it rests; the first sentence is P047-T2. [Formal reading. The rejoinder prints no formula. This is the statement that the audit's two validators derived (validator artifact, section 8; second validator, section 5), with positivity in the sense of the target article that the bullet recapitulates.] Let $(W_i, A_i, Y_i(0), Y_i(1))$, $i = 1, \ldots, n$, be i.i.d., with $A_i \in \{0, 1\}$, observed outcome $Y_i = A_iY_i(1) + (1 - A_i)Y_i(0)$, ignorability $A_i \perp Y_i(a) \mid W_i$ for $a = 0, 1$, and known propensity score $e(w) = \Pr(A_i = 1 \mid W_i = w)$. Let $0 < B < \infty$ and $0 < \varepsilon \le 1/2$ be fixed known constants with $|Y_i(a)| \le B$ for $a = 0, 1$ and $\varepsilon \le e(W_i) \le 1 - \varepsilon$ almost surely. Let $\tau = E[Y_i(1) - Y_i(0)]$, $Z_i = \frac{A_iY_i}{e(W_i)} - \frac{(1 - A_i)Y_i}{1 - e(W_i)}$ and $T_n = \frac{1}{n}\sum_{i=1}^{n} Z_i$. Then, for every $n \ge 1$: (i) $E[Z_i \mid W_i] = E[Y_i(1) - Y_i(0) \mid W_i]$, hence $E[Z_i] = \tau$ and $E[T_n] = \tau$; (ii) $|Z_i| \le B/\varepsilon$; (iii) for every $t \ge 0$, $\Pr(|T_n - \tau| \ge t) \le 2\exp\left(-\frac{n t^2 \varepsilon^2}{2B^2}\right)$; (iv) for every $0 < \alpha < 1$, with $h_n = \frac{B}{\varepsilon}\sqrt{\frac{2\log(2/\alpha)}{n}}$ and $C_n = [T_n - h_n,\ T_n + h_n]$, $\Pr(\tau \in C_n) \ge 1 - \alpha$; (v) the width of $C_n$ is the deterministic number $2h_n = \frac{2B}{\varepsilon}\sqrt{2\log(2/\alpha)}\; n^{-1/2}$, so $\sqrt{n}$ times the width does not depend on $n$. Statements (i)-(v) hold for every law that satisfies the conditions above with the same $B$ and $\varepsilon$; nothing is assumed about the distribution of $W_i$, the form of $e$, or the functions $w \mapsto E[Y_i(a) \mid W_i = w]$. (vi) [One potential-outcome mean, the form checked by one of the fresh readers.] Under the same i.i.d. sampling, consistency and ignorability, if $0 \le Y_i(1) \le 1$ and $e(W_i) \ge \varepsilon$ almost surely, then with $\theta = E[Y_i(1)]$ and $\hat\theta_n = \frac{1}{n}\sum_{i=1}^{n}\frac{A_iY_i}{e(W_i)}$: $E[\hat\theta_n] = \theta$; $0 \le \frac{A_iY_i}{e(W_i)} \le \frac{1}{\varepsilon}$; $\Pr(|\hat\theta_n - \theta| \ge t) \le 2\exp(-2n\varepsilon^2t^2)$ for every $t \ge 0$; and $\hat\theta_n \pm \frac{1}{\varepsilon}\sqrt{\frac{\log(2/\alpha)}{2n}}$ covers $\theta$ with probability at least $1 - \alpha$ for every $n \ge 1$ and every $0 < \alpha < 1$.
: T1Statement
Theorem: SAP.P047.T1
Statement hash: bdf8c71a29d919842eda9ecdcffae478298aa730086de4707ef1279c7999721e
Statement definition: SAP.P047.T1Statement
Certificate. 20261104T173313Z
Declaration review: faithful; 2026-11-04T17:56:00Z; binding v2
Evidence scope: Certification checks formal proof objects. Statement fidelity is a model judgment. Author review is separate.
Proof dependencies: Independently extracted
Manifest annotation reconciliation: Effective use follows the source-bound dependency observation; original annotations are retained in the crosswalk.
AronowAudit.P047.armIPW_abs_le: observed used
AronowAudit.P047.armPropensity_ge: observed used
AronowAudit.P047.bounded_independent_average_tail: observed used
AronowAudit.P047.conditional_armIPW: observed used
AronowAudit.P047.conditional_score_identity: observed used
AronowAudit.P047.confidenceInterval_coverage: observed used
AronowAudit.P047.confidenceInterval_root_width: observed used
AronowAudit.P047.covariateSigma_le: observed used
AronowAudit.P047.estimator_hoeffding: observed used
AronowAudit.P047.estimator_unbiased: observed used
AronowAudit.P047.halfWidth_exponential: observed used
AronowAudit.P047.integrable_armIPW: observed used
AronowAudit.P047.integrable_arm_numerator: observed used
AronowAudit.P047.integrable_potential: observed used
AronowAudit.P047.measurable_arm: observed used
AronowAudit.P047.measurable_armIPW: observed used
AronowAudit.P047.measurable_armPropensity_conditioning: observed used
AronowAudit.P047.measurable_covariate: observed used
AronowAudit.P047.measurable_covariate_conditioning: observed used
AronowAudit.P047.measurable_estimator: observed used
AronowAudit.P047.measurable_potential: observed used
AronowAudit.P047.measurable_score: observed used
AronowAudit.P047.sample_coordinate_hasLaw: observed used
AronowAudit.P047.sample_score_identDistrib: observed used
AronowAudit.P047.sample_scores_independent: observed used
AronowAudit.P047.score_abs_le: observed used
AronowAudit.P047.score_eq_armIPW: observed used
AronowAudit.P047.score_unbiased: observed used
AronowAudit.P047.subgaussian_abs_tail: observed used
AronowAudit.P047.symmetric_interval_coverage: observed used
Source and evidence metadata · sap-2026-11-08-assured-release